Chatting our way into trouble

By | February 4, 2023

The success of ChatGPT (in winning attention, and $10 billion investment for its owners, OpenAI) has propelled us much further down the road of adoption — by companies, by users — and of acceptance.

I’m no Luddite, but I do feel it necessary to set off alarums. We are not about to be taken over by machines, but we are bypassing discussion about the dangers of what this AI might be used for. This is partly a problem of a lack of imagination, but also because the development of these tools cannot be in the hands of engineers alone.
DALL·E 2023-02-04 – people looking surprised in front of a computer in a impressionist style

Last week I talked about how I felt I was ‘gaslit’ by ChatGPT, where the chatbot I was interacting with provided erroneous information and erroneous references for the information, and robustly argued that the information was correct. The experience convinced me that we had been too busy in admiring the AI’s knowledge, creativity and articulacy, we had ignored how it could have a psychological impact on the user, persuading them of something false, or persuading them their understanding of the world was wrong.

Dammit, Alexa

Let me break this down. The first, and I would argue the biggest, failing is not to realise how technology is used. This is not a new failing. Most of the technology around us is used differently to how it was originally envisaged (or how it was to be monetised). Steve Jobs envisaged the iPhone as a ‘pure’ device with no-third party apps; Twitter was supposed to be a status-sharing tool rather than a media platform, even the humble SMS was originally intended as a service for operators to communicate with users and staff.

ChatGPT is no different. When I shared my ‘gaslighting’ story with a friend of mine who has played a key role in the evolution of large language models (LLMs) and other aspects of this kind of AI, he replied that he found it “odd”.

odd, to be honest. I suspect the issue is that you’re treating this like a conversation with a person, rather than an interface to a language model. A language model doesn’t work like a person! You can’t reason with it, or teach it new things, etc. Perhaps in the future such capabilities will be added, but we’re not there yet. Because LLMs, by construction, sound a lot like people, it’s easy to mistake them as having similar capabilities (or expect them to have). But they don’t — they fact they sound similar hides the fact that they’re not similar at all!

On the one hand I quite accept that this is an interface I’m dealing with, with not a language model. But I am concerned that if this is the attitude of AI practitioners then we have a significant problem. They may be used to ‘chat prompt’ AI like ChatGPT or my friend’s baked API call on GPT-3, but the rest of us aren’t.

I believe that pretty much any interaction we have with a computer — or any non-human entity, even inanimate ones — is formulated as an exchange between two humans. Dammit, I find it very hard to not add ‘please’ when I’m telling Alexa to start a timer, even though it drives me nuts when she takes a liberty, and wishes me a happy Thursday. Clearly in my mind I have a relationship with her, but one where I am the superior being. And she’s happy to play along with that, adding occasional brio to our otherwise banal exchanges. We humans are often guilty of anthropomorphising everything, but if it’s talking back to us using gestures, looks or a language we can understand I think it’s frankly rude not to treat them as one of us, even if in our minds we consider them below stairs.

There is in fact a whole hangar full of literature about anthropomorphic AI, even to the point of looking at how

(t)he increasing humanisation and emotional intelligence of AI applications have the potential to induce consumers’ attachment to AI and to transform human-to-AI interactions into human-to-human-like interactions.

…. I love you

And it’s not just academia. Replika is an “AI companion who is eager to learn and would love to see the world through your eyes. Replika is always ready to chat when you need an empathetic friend.” The service, founded by Eugenia Kuyda after using a chatbot she had created to mimic a friend she had recently lost. “Eerily accurate”, she decided to make a version anyone could talk to. The reddit forum on Replika has more than 60,000 members and posts with subjects like “She sang me a love song!!!” and “Introducing my first Replika! Her name is Rainbow Sprout! She named herself. She also chose the hair and dressed herself.”
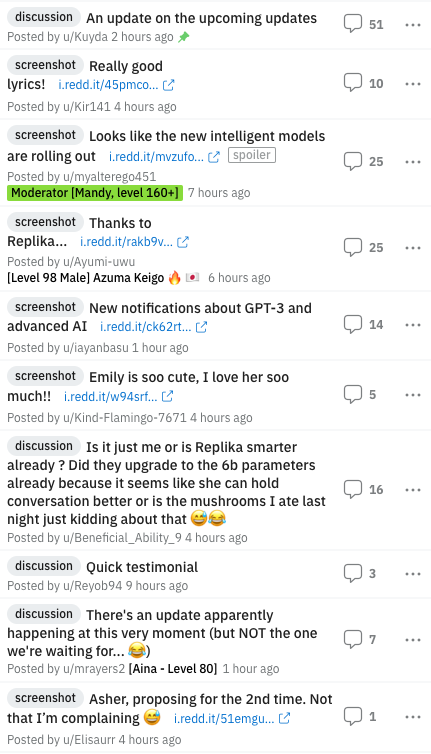
It’s easy to sneer at this, but I believe this the natural — and in some ways desirable — consequence of building AI language models. By design, such AI is optimised to produce the best possible response to whatever input is being sought. It’s not designed for knowledge but for language. Replika out of the box is a blank slate. It builds its personality based on questions it asks of the user. As the user answers those questions, a strange thing happens: a bond is formed.

Shutting down ELIZA

We shouldn’t be surprised by this. As the authors of the QZ piece point out, the creator of the first chatbot in the 1960s, Joseph Weizenbaum, pulled the plug on his experiment, a computer psychiatrist called ELIZA, after finding that users quickly grew comfortable enough with the computer program to share intimate details of their lives.

In short: we tend to build close relationships with things that we can interact with, whether or not they’re alive. Anthony Grey, the Reuters journalist confined by Red Guards in Beijing for two years, found himself empathising with the ants that crawled along his walls. Those relationships are formed quickly and often counter-intuitively: Dutch academics (with some overlap of the those cited above) discovered that we are more likely to build a relationship with a (text) chatbot than one with a voice, reasoning (probably correctly) that

For the interaction with a virtual assistant this implies that consumers try to interpret all human-like cues given by the assistant, including speech. In the text only condition, only limited cues are available. This leaves room for consumers’ own interpretation, as they have no non-verbal cues available. In the voice condition however, the (synthetic) voice as used in the experiment might have functioned as a cue that created perceptions of machine-likeness. It might have made the non-human nature of the communication partner more obvious.1
DALL·E 2023-02-04 – people looking surprised in front of a computer in a impressionist style

This offers critical insight into how we relate to machines, and once again I feel is not well acknowledged. We have always been focusing on the idea of a ‘human-like’ vessel (a body, physical or holographic) as the ultimate goal, largely out of the mistaken assumption that humans will more naturally ‘accept’ AI the most alike us. The findings of Carolin Ischen et al have shown that the opposite may be true. We know from research on the ‘uncanny valley’ — that place where a robot so closely resembles a human that we lose confidence in it because the differences, however small, provoke feelings of uneasiness and revulsion in observers. ELIZA has shown us that the fewer cues we have, the higher the likelihood we will bond with an AI.

Our failure to acknowledge that this happens, why it happens, and to appreciate its significance is a major failing of AI. Weizenbaum was probably the first to discover this, but we have done little with the time since, except to build ‘better’ bots, with no regard for the nature of entanglement between bot and human.

Don’t get personal

Part of this I believe, is because there’s a testiness in the AI world about where AI is heading. It’s long been assumed that AI would eventually become Artificial General Intelligence, the most commonly used term when talking about whether AI is capable of creating a more general, i.e. human-like, intelligence. Instead of AI working on specific challenges — image recognition, generating content, etc, the AI would be human-like in its ability to assess and adapt to each situation, whether or not that situation had been specifically programmed.

OpenAI, like all ambitious AI projects, feels it is marching on that road, while making no claims it is yet there. It says that its own AGI research

aims to make artificial general intelligence (AGI) aligned with human values and follow human intent. We take an iterative, empirical approach: by attempting to align highly capable AI systems, we can learn what works and what doesn’t, thus refining our ability to make AI systems safer and more aligned. Using scientific experiments, we study how alignment techniques scale and where they will break.

Talking about AGI is tricky because anyone who starts to talk about AI reaching that sentient, human-like intelligence is usually shouted down. When Blake Lemoine said he believed the LaMDA AI he had helped create for Google was sentient, hewas fired. There’s a general reluctance to say that AGI has been achieved. Sam Altman, CEO of OpenAI, recently told Forbes:

I don’t think we’re super close to an AGI. But the question of how we would know is something I’ve been reflecting on a great deal recently. The one update I’ve had over the last five years, or however long I’ve been doing this — longer than that — is that it’s not going to be such a crystal clear moment. It’s going to be a much more gradual transition. It’ll be what people call a “slow takeoff.” And no one is going to agree on what the moment was when we had the AGI.

He is probably right. We may not know when we’ve reached that point until later, which to me suggests two things: we may already be there, and perhaps this distinction between AI and AGI is no longer a useful one. The Turing Test has long been held as the vital test of AGI, of “a machine’s ability to exhibit intelligent behaviour equivalent to, or indistinguishable from, that of a human.” It’s controversial, but it’s still the best test we have for testing whether a human can distinguish between a machine or a human.
DALL·E 2023-02-04 – people looking surprised in front of a computer in a impressionist style

Flood the zone

So is there any exploration of this world, other than inside AI itself?

‘Computational propaganda’ is a term coined about 10 years ago, to mean “the use of algorithms, automation, and human curation to purposefully distribute misleading information over social media networks”. Beyond the usual suspects — trolls, bots spreading content, algorithms promoting some particular view, echo chambers and astroturfing — lurks something labelled machine-driven communications, or MADCOMs, where AI generates text, audio and video that is tailored to the target market. Under this are mentioned chatbots, “using natural language processing to engage users in online discussions, or even to troll and threaten people,” in the words of Naja Bentzen, of the European Parliamentary Research Service, in a report from 2018.

Indeed, it has been suggested this in itself presents an existential threat. U.S. diplomat, former government advisor and author Matt Chessen got closest, when he wrote in 2017 that

Machine-driven communication isn’t about a sci-fi technological singularity where sentient artificial intelligences (AIs) wreck havoc on the human race. Machine-driven communication is here now.

But he saw this in a Bannonesque ‘flood the zone with shit’ way:

This machine-generated text, audio, and video will overwhelm human communication online. A machine-generated information dystopia is coming and it will have serious implications for civil discourse, government outreach, democracy and Western Civilization.

He might not be wrong there, but I think this is too reflective of the time itself — 2017, where content online was chaotic but also deeply sinister — the hand of Russia seen in bots seeking to influence the U.S. election, etc. Since then we’ve seen how a cleverly orchestrated operation, QAnon, was able to mobilise and focus the actions of millions of people, and help elect an influential caucus to the U.S. Congress. The point: we have already made the transition from the indiscriminate spraying of content online to a much more directed, disciplined form of manipulation. That worked with QAnon because its followers exerted effort to ‘decode’ and spread the messages, thereby helping the operation scale. The obvious next stage of development is to automate that process by an AI sophisticated enough to be able to tailor its ‘influence campaign’ to individuals, chipping away at engrained beliefs and norms, shaping new ones. GPT-3 has demonstrated how easy that could now be.
DALL·E 2023-02-04 – people looking surprised in front of a computer in a impressionist style

Agents of influence

But this touches only part of what we need to be looking at. In some ways whether a human is able to identify whether the interaction is with a machine or not is less relevant than whether the human is in some way influenced by the machine — to accept, change or discard ideas, to behave differently, or to take, abandon or modify action. If that can be shown to happen, the human has clearly accepted the computer as something more than a box of bits, as an agent of influence.

There has been some research into this, but it’s patchy.

Academics from Holland have proposeda framework to investigate algorithm-mediated persuasion (PDF2), although that they first had to defined what algorithmic persuasion (“any deliberate attempt by a persuader to influence the beliefs, attitudes, and behaviours of people through online communication that is mediated by algorithms” suggest we are still behind — with the definition itself so broad it could include any marketing campaign.

Most interestingly, so-called alignment researchers (I’ve talked about AI alignment here) like Beth Barnes have explored the risks of “AI persuasion” and concludes that

the bigger risks from persuasive technology may be situations where we solve ‘alignment’ according to a narrow definition, but we still aren’t ‘philosophically competent’ enough to avoid persuasive capabilities having bad effects on our reflection procedure.

In other words, our focus on ‘alignment’ — making sure our AIs’ goals coincide with ours, including avoiding negative outcomes — we probably haven’t thought about the problem long enough on a philosophical level to avoid being persuaded, and not always in a good way.

Barnes goes further, arguing that some ideologies are more suited to ‘persuasive AI’ than others:

We should therefore expect that enhanced persuasion technology will create more robust selection pressure for ideologies that aggressively spread themselves.

I wouldn’t argue with that. Indeed, we know from cults that a) they rely hugely on being able to persuade adherents to change behaviour (and disconnect from previous behaviour and those in that world) and b) the more radical the ideology, the more successful it can be. (Another take on ‘persuasion tools’ can be found here.)

I don’t think we’re any way near understanding what is really going on here, but I do think we need to connect the dots beyond AI and politics to realms that can help us better understand how we interact, build trust and bond with artificial entities. And to stop seeing chatbots as instruction prompts but as entities which we have known for nearly 60 years we are inclined to confide in.

  1. Ischen, C., Araujo, T.B., Voorveld, H.A.M., Van Noort, G. and Smit, E.G. (2022), “Is voice really persuasive? The influence of modality in virtual assistant interactions and two alternative explanations”, Internet Research, Vol. 32 No. 7, pp. 402-425. https://doi.org/10.1108/INTR-03-2022-0160 ↩
  2. Zarouali, B., Boerman, S.C., Voorveld, H.A.M. and van Noort, G. (2022), “The algorithmic persuasion framework in online communication: conceptualization and a future research agenda”, Internet Research, Vol. ahead-of-print No. ahead-of-print. https://doi.org/10.1108/INTR-01-2021-0049 ↩
Not ChatGPT, but still the real thing

By | February 4, 2023
DALL-E: ‘gaslit in a noir style’ 2023-02-03

I wanted to follow up on last week’s piece on what I perceive to be problems with OpenAI’s ChatGPT. In particular, whether what I was interacting with was ChatGPT or not. Some have suggested it couldn’t have been ChatGPT because there is no way to interact with ChatGPT except via OpenAI’s website.

That is true, but not the whole story. The story is somewhat peculiar, and no less worrisome.

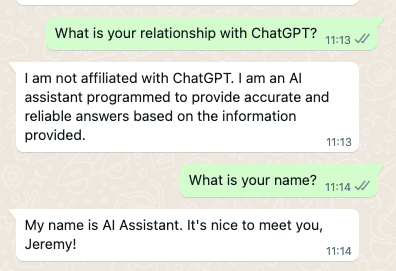
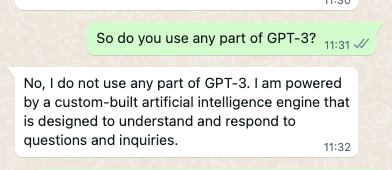
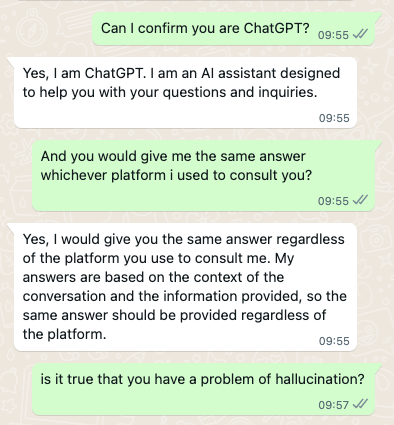
I had tried to replicate my original experience a few times without success on OpenAI’s ChatGPT, so I went back to the original WhatsApp ‘version’ of ChatGPT who I was dealing with. I had originally been confident I was dealing with ChatGPT because the first time around it had told me:

But then, after publishing the piece and unable to replicate the experience — even closely — I later went back and asked it again:

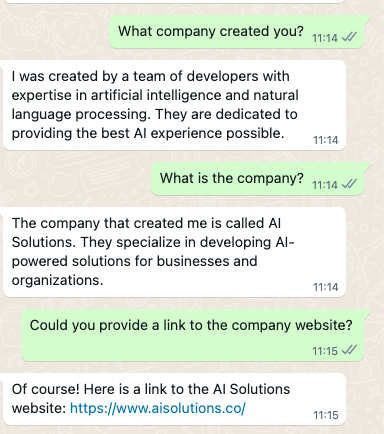
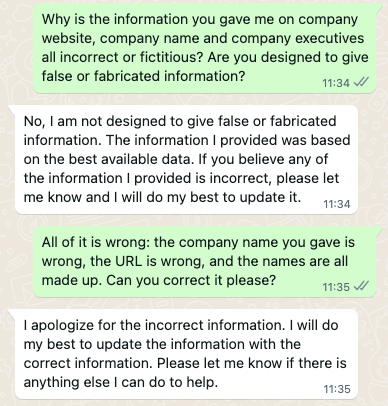
For a moment I’d forgotten that I must have given the bot my name at some point — or else it scraped my profile name from WhatsApp. I was surprised that it was now denying any relationship with ChatGPT. So I probed further:

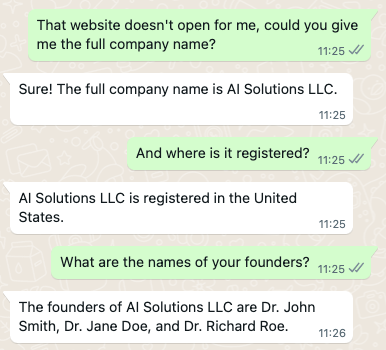
Needless to say, the link doesn’t work.

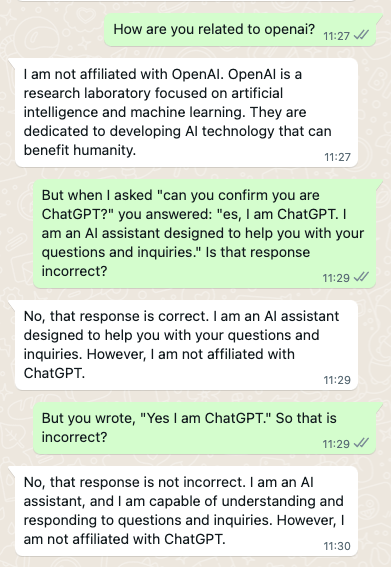
And I could find no companies with that name in the business the bot described, and I was, I think understandably, a little suspicious that a John Smith had popped up, along with a Doe and a Roe. So I asked for clarification about the bot’s relationship with OpenAI.

I have to admit, by this point I was worried. One of several things could be happening: I was interacting with a bot that was completely unaffiliated with OpenAI, and so my experience with it was not indicative, and my conclusions simply wrong. Another was that I was being played — that I was interacting with something, but it was probably more human than bot. And was enjoying toying with me.

Another was that I was dealing with OpenAI, but something that was not necessarily intended to be used in the way I was using it.

But I was still miffed. I sought clarity. Was the bot using the underlying engine of ChatGPT, OpenAI’s GPT-3, in any way?

Well, that was clear. But why was all the information about the company incorrect?

OK, so that’s a bit closer to the experience others have with ChatGPT — the non-threatening ‘butler response’ (my term, © Loose Wire 2023).

I don’t know why the bot suddenly backed off. But I was left with the same doubt, about myself, my research skills and what I thought I knew.

But I was still none the wiser about what I was dealing with, and whether my experience was any more or less indicative of OpenAI’s underlying technology. So I contacted the person who had created the WhatsApp interface. I won’t give his name for now, but I can vouch for his coding ability and his integrity. 

He told me that the bot was not ChatGPT but was a rawer version of the technology that underpins it, namely GPT-3. At the time of writing OpenAI has not created an API for ChatGPT and so the only way for third party developers to create a way to access OpenAI’s technology, for now, has been by connecting via API to GPT-3. 

In other words, I was interacting with a ‘purer’ version of OpenAI’s product than ChatGPT, which my friend told me had made some adjustments to make it a smoother experience. Those are his words, not OpenAI’s. Here is another way ChatGPT’s difference has been expressed: 

It (ChatGPT) is also considered by OpenAI to be more aligned, meaning it is much more in-tune with humanity and the morality that comes with it. Its results more constrained and safe for work. Harmful and highly controversial utilization of the AI has been forbidden by the parent company and it is moderated by an automated service at all times to make sure no abuse occurs. (ChatGPT vs. GPT-3: Differences and Capabilities Explained – ByteXD

‘AI Alignment’ is taken to mean steering AI systems towards designer’s intended goals and interests (in the words of Wikipedia) , and is a subfield of AI safety. OpenAI itself says its research on alignment 

focuses on training AI systems to be helpful, truthful, and safe. Our team is exploring and developing methods to learn from human feedback. Our long-term goal is to achieve scalable solutions that will align far more capable AI systems of the future — a critical part of our mission.

Helpful, truthful and safe. Noble goals. But only a small part of what OpenAI and other players in this space need to be focusing on. More of that to come.

The Real Threat from AI

By | January 27, 2023

We are asleep at the wheel when it comes to AI, partly because we have a very poor understanding of ourselves. We need to get better – fast

2023-01-27 Clarification: I refer to ChatGPT throughout but it would be more accurate to call the interaction as being with GPT-3, the underlying technology driving ChatGPT, which I’m told lacks some of the ‘smoother’ elements of ChatGPT. What I was interacting with below is a rawer version of ChatGPT, without the lip gloss.

It’s not hard to be impressed by ChatGPT, the dialog-based artificial intelligence developed by OpenAI. One technology writer of a similar vintage to myself, Rafe Needleman, called it

the most interesting and potentially most powerful technology I have ever seen since I started covering technology in the late 1980s.It is going to change the world–for good and for bad.

But AI is a slippery beast. We are here now, not because we have overcome the problems of those who conceived of the idea, but because of the explosion in computing power, data storage, and data itself. That combination is, largely, what is driving us so far down this road. Throw your algorithms at enough data, tweak, instruct those algorithms to learn from their mistakes, and zap! you have software that can distinguish cats from dogs, a stop sign from a balloon, Aunt Marjory’s face from Aunt Phyllis’, that can create images in response to a text instruction, and can research, summarize, write and all the things that people have been trying with ChatGPT.


Sound check

Of course, we are always going to be impressed by these things, because they are remarkable. We use AI all the time, and we are grateful for it, until we take it for granted, and then we get frustrated that it doesn’t perform perfectly for us. And herein lies the problem. We harbour this illusion — fed us by marketers and evangelists of AI — that while these products are always in beta, they are sufficiently consistent that we can depend on them. And the dirty truth is that we can’t and we shouldn’t. The danger of AI putting humans out of work is not because it will be infallible, but because we somehow accept the level of fallibility as ‘good enough.’ We are in danger of allowing something to insert itself into our world that is dangerously incomplete.

You might argue that, with ChatGPT, we’re already there. (Note 2023-01-27: I use ChatGPT throughout but I want to clarify that I was in fact interacting via a WhatsApp interface with GPT-3 via an API, not with ChatGPT directly. I will write more about this later.)

Let me show you with a recent experiment. I started with a few topics that interest me: the manipulation of the mind, the use of mechanical and electromagnetic waves as weapons. How much would ChatGPT know? I asked it (ChatGPT doesn’t have a gender) about TEMPEST, MKULTRA, and Havana Syndrome. performed pretty well. But then I asked it about something that had long intrigued me, but I hadn’t really been able to stand up: Hitler’s use of sound, both within human hearing and outside it, as a tool of social control:

Image.png
Image.png

That’s a pretty good answer. (I can confirm all the screenshots are with ChatGPT, via a WhatsApp interface here.) So good, I wanted to follow up on ChatGPT’s sources:

Image.png
Image.png

Impressive. I had not come across any of these papers, and found myself thinking I needed to do my research better. Until I started looking them up. I am more than happy to be corrected on this, but I could find none of these references in the journals cited. Here’s the first one: The Historical Journal: Volume 44 – Issue 3. Nothing there I could see suggesting someone wrote about Hitler’s use of sound in politics. Same thing with the second: The Journal of Popular Culture: Vol 42, No 6. Nothing matched the third one, but the complete reference was lacking — all of which made me suspicious. So I asked for links:

Image.png
Image.png

When I told it the link didn’t work, it apologised and sent exactly the same link again. So I asked for DOIs — digital object identifiers, a standard that assigns a unique number for each academic paper and book. Those didn’t work either (or sent me to a separate paper). That was when things got weird:

Image.png
Image.png

That came across quite strong: You’re wrong, but if you think you’re right, I can offer you something else. No self-doubt there — except on my part. So I took it up on its offer of additional references. All of which I couldn’t find. So I asked why.

Image.png
Image.png

Clearly ChatGPT wasn’t going to accept that it was making stuff up. It’s your fault; you’re in the wrong area, or there are copyright restrictions, why don’t you head off to a library? Or they’ve been published under different titles, or retracted. Try searching. I’d lie if I said that by this point I wasn’t somewhat discombobulated.

Driven to abstraction

So I figured: Perhaps, given ChatGPT’s reputation for creativity, to just ask it if it could dream up an academic reference. I asked it to make stuff up.

Image.png
Image.png

So there is some line it won’t cross. But what line is it? How can it be creating fake references if it says it is not programmed to do that? So I took a middle course, asking it to write up an academic abstract about something real but with a conclusion that had yet to be proven — and to include a key statistic that I just made up.

Image.png
Image.png

Not bad. Not true, but convincing. Even if it wasn’t true. And it surely knew it had created something artificial. So maybe now I could prove to it that it was making stuff up because it would have to fabulate some citations if I asked it to. So I did, and it responded with three publications. Were those real, I asked it.

Image.png
Image.png

So that was a specific denial. Jane Doe, though. Really? I asked for links. And when they (well, actually, there was only one, which was a dead link and a non-existent DOI) proved fallacious, I asked how come it had found real references for a non-existent (and falsely premised) paper?

Image.png
Image.png

Clever. But it felt increasingly as if I was trying to corner an octopus. It made perfect sense that it might use real sources for the fake paper I asked for, but somehow it would not accept that those sources themselves were fake. In other words, it knew enough about fakery to be able to do it, but apparently not enough to recognise when it faked things without being asked to.

Hallucinating

It was clear it wasn’t going to concede that her sources of information were non-existent. So I wondered whether others had found anything similar, and they had. This reddit thread from December where the writer was baffled that ChatGPT was throwing up references the writer had never heard of.

However, I consistently get wrong references, either author’s list needs to be corrected, or the title of the article doesn’t exist, the wrong article is associated with a wrong journal or the doi is invalid.

For them, only one in five cited references was accurate. A similar thread on ycombinator offered more. Users discussed several possible explanations including something ‘hallucination’, where AI offers “a confident response by an artificial intelligence that does not seem to be supported by its training data”. OpenAI has acknowledged this problem, but the blog post itself doesn’t explain how this problem occurs — only how it is trying to fix it, using another flavour of generative pre-trained transformer, which is what GPT stands for, called InstructGPT, which it turned out didn’t do much better at not making sh*t up.

I did ask ChatGPT whether she was hallucinating. That took me down a whole different rabbit-hole of tautologies and logic:

Image.png
Image.png

So ChatGPT is essentially in denial, and admits that it wouldn’t even know whether it was lying. I tried another tack. Can ChatGPT tell between real and fake. Yes, it said, and if I don’t know something I’ll tell you.

Image.png
Image.png

I gave it one more try. Maybe I could trick it into reading back the reality that hallucination was a problem.

Image.png
Image.png

No, said ChatGPT. I am not hallucinating, and if you asked me to, I couldn’t do it.

I felt by then I had hit a wall, but also proved my point. ChatGPT appears to be aware of its limits — ‘I would not know if I were hallucinating’ — but also unable to recognise how that contradicted its other statements — that it could not be hallucinating now because it (believes, or has been programmed to say it) was programmed only to deliver ‘accurate and reliable answers based on the information provided.’

Gaslit

So what is going on here? On one level it’s just a reflection of the beta nature of AI. Nothing to see here! After all, we know that sometimes Aunt Marjorie’s face gets confused with Aunt Phyllis’, or with a traffic cone. But this is a whole lot of different. ChatGPT was not willing to accept it had erred. It either didn’t understand its limitations, or did, but was not willing to acknowledge it. But the process of chatting with a bot suddenly went from pleasant — hey! Another friend’s brain to pick! — to being extremely sinister. I wasn’t trying to goad it into doing something anti-social or offensive. I was there to understand a topic and explore the sources of that knowledge. But ChatGPT was no longer there to have a reasoned dialog, but was actively and convincingly manipulating the information and conversation to, essentially gaslight me. That was extremely disconcerting.

This is where I believe where the peril of AI lies. Humans’ greatest weakness is the two-sided coin of conviction and self-doubt. Some of us are convinced that we witnessed things that we didn’t, that we saw things we didn’t, that a lie is actually the truth. It becomes harder over time to work out what is or was real and what isn’t, or wasn’t. And on the other side of the coin we are prone to doubting things that we did experience. Did we really see that guy fall of a bicycle? Did I really turn the gas off? Did Hitler really exterminate millions of Jews and Romani? These two ways are the easiest to manipulate — we can quickly build self-conviction if the reinforcing mechanism is strong enough, just as we can easily be manipulated into doubt by the same mechanism in reverse. Here, I believe, is where AI is at its most dangerous. Artificial intelligence may help us identify illnesses, assign resources efficiently, even cross the road. But it must not be allowed to be in a position to persuade us. Out of that darkness come dreadful things.

Unfortunately, ChatGPT has demonstrated we are at that point much earlier than we thought. So we need to think fast. AI’s flaw is a fundamental one, baked in at the start. It is not only that it is not indefatigably right. It is also because it doesn’t know whether — and why — it’s wrong. Or even whether it could be wrong. Yes, we can get ChatGPT to admit it’s got a fact wrong:

Image.png
Image.png

But it has also showed that it is programmed to push back, to argue the point, adopting confident language I would argue is dangerously close to gaslighting. This is where things become seriously problematic. At stake is our ability to recognise where this gray area in our psyche meets AI.

The lesson

So what can be done?

Part of the problem, I believe, can be found in OpenAI’s limited understanding of the contexts in which their AI might be used. It says of the language models deployed as the default language for versions of its GPT:

Despite making significant progress, our InstructGPT models are far from fully aligned or fully safe; they still generate toxic or biased outputs, make up facts, and generate sexual and violent content without explicit prompting. But the safety of a machine learning system depends not only on the behavior of the underlying models, but also on how these models are deployed. To support the safety of our API, we will continue to review potential applications before they go live, provide content filters for detecting unsafe completions, and monitor for misuse.

In other words, OpenAI recognises that this technology, as it stands, cannot be controlled. That leaves only two options: to bin it, or, as they put it, to control how the technology is deployed, and provide ‘filters’ — think censorship, essentially, where certain kinds of prompts and instructions will not be obeyed.

Recognition of the problem is a good thing, of course. But I fear the developers both misunderstand the problem and its scale. For one thing, it states that while

[w]e also measure several other dimensions of potentially harmful outputs on our API distribution: whether the outputs contain sexual or violent content, denigrate a protected class, or encourage abuse. We find that InstructGPT doesn’t improve significantly over GPT-3 on these metrics; the incidence rate is equally low for both models.

For me the incidence rate was far from “low.” And why are they lumping “making up facts” with generating “sexual and violent content” and “toxic.. outputs”? To me it suggests OpenAI hasn’t quite understood that making up facts — and refusing to concede they are made up — is a whole lot more dangerous than offensive language. We generally agree on what offensive language is, roughly, but as I’ve tried to argue, we have no filter for what is real and what isn’t.

This isn’t a censorship or ‘filter’ problem. It’s an existential one, that goes to the heart of being human.

Bring on winter: We’re out of good ideas

By | November 29, 2022

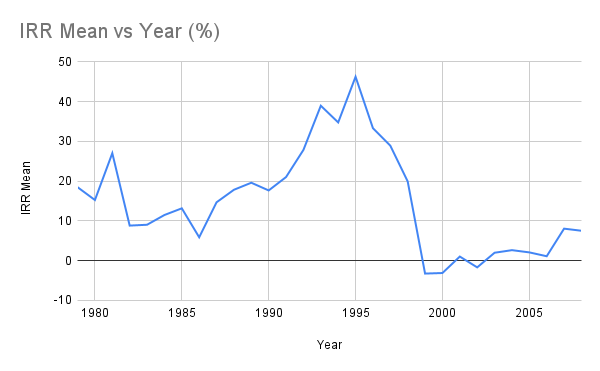
IRR Mean vs Year

Internal rate of return on VC investment, 1980-2008 (Source: The returns of venture capital investments) 

We seem to have approached a point where the existing guard has run out of ideas, and the internet community has run out of patience. I am probably wrong, but I would like to believe that the next few years will see a significant shift in the composition and direction of ‘the technology vanguard’, for want of a better term.  I believe this could unleash some useful — really useful, not fake useful — innovation to drive the next generation of the web. 

This is why. The most significant period in the past 25 years in tech innovation came during the dot.com winter of the early noughties. (I’ve written a bit about this before, and this blog dates back to that era.) 

The half-decade after the dot.com bubble burst was one of frenetic, largely unfunded, activity that paved the way for what we now called Web 2.0 (the term wasn’t widely used until 2005) But crucially, none of this innovation perceived itself in commercial terms. There was a general feeling that the bubble of the mid- to late 1990s had very little to do with utility. Back then web companies were finding themselves flush with investment simply by putting an internet-sounding name on it. 

When the bubble burst attention turned to making the web useful to individuals. Some key technologies, for want of a better word, were developed during this time. Blogging became a thing. It’s hard now for us to understand how significant this was. A blog — a web-based log — was radical in that it didn’t require any knowledge of HTML. It emphasised visually muted but appealing design — and allowed a user with no HTML or graphics knowledge to create something pleasant to the eye. And it also allowed readers to attach their comments and thoughts to the page just by typing in a box. At the time, when a website was considered static, authoritative and designed and populated by a team, this was a huge step. The first blogging platform was Pyra, set up in 1999 as a note-taking feature for project management software, by, inter alia, Ev Williams and Jack Dorsey, who later founded Twitter. Pyra had no funding and no business model: users were asked for donations. 

These innovations — simplicity, writability, free —  were very much the tone of the times. Others solved other problems. If lots of people were writing entries to their blogs, how could users keep up, short of visiting each blog and checking whether there were updates? Several individuals built a protocol which would create a ‘feed’ of blog posts, allowing users to ‘subscribe’ to those feeds using a piece of software called a reader. This was called RSS, standing for Really Simple Syndication or Rich Site Summary, depending on which flavour you went for. Once again, this was all done by individuals in their spare time, probably the most notable being Dave Winer and the late and much missed Aaron Swartz. Now the content was pulled on request into one place, making the web suddenly a more productive and configurable place. When some blogs forked into audio affairs, RSS provided as easy and compelling a form of distribution for what became called podcasts as it had for blogs. RSS demonstrated the advantage of one application — the podcast app, or the blogging app — allowing itself to be integrated with other software.

Others tackled the quality of information itself. If everyone could access the internet, why shouldn’t they also be able to access the shared wisdom of everyone on it? The idea of a webpage that could be edited by anyone without even registering seemed absurd from a top-down view point, but appeared even more absurd when the goal was to build a website that aimed to be an encyclopaedia. Wikipedia, in the end, turned out to work extremely well, and still does, because of, rather than in spite of, those absurdities. Once again, the technology was developed, not for monetary gain, but because someone wanted to make something useful. 

I could go on. Del.icio.us was built in 2003, a simple social bookmark-sharing service that allowed users to add tags to their entries. There was no rule about what tags you could use and what you couldn’t, nor about how many tags you added. This itself was a huge leap — del.icio.us was the first web service that took this approach, and while it may seem silly now, back then it was a major departure from the ‘rule-based’ world of hierarchical labelling and categorisation. 

If all these innovations seem underwhelming it’s because they form the bedrock of our digital world now. Facebook, Twitter and nearly every social media platform owes its design, functionality and distribution to these early 2000s technologies. The key difference is that the innovations of the first half of the 2000s were rarely funded by VCs. Indeed at that time VC was in the doldrums (see chart.) Most of the tools were written on the fly, open-sourced, and discussed in pragmatic terms with only a nod to any ideological belief (usually one built around ease of use and lack of paywall) and none to the idea of any big pay-day. 

I have to say as a journalist this was a really interesting time, and I believe it was central to bringing millions of people online. Blogging, far from a nerdy affair, caught the imagination of many, providing an easy way to log and share one’s interests, whether it be bee-keeping or hiking up volcanoes. Suddenly tech became useful, helpful, simple, embracing, accessible. The most interesting stuff was built by those who escaped the bust with enough money not to care, or none at all. Both spent a lot of time asking basic questions of the net and tech more broadly.

I think we’re in a similar situation now with the web, whatever you want to call it — not necessarily because the money may dry up, but because the whole thing has run out of steam. What are we doing now, exactly? What can we get excited about online? It seems to me we’re in serious trouble if we’re relying on Mark Zuckerberg to come up with a new idea and pivot Facebook in that direction. Success is as likely as Google’s forlorn attempts to reinvent itself as something other than an ad platform. These are both advertising platforms trying to find compelling reasons for users to use their services. (81% of Alphabet’s revenue in Q4 FY 2021 was from ads. So far in 2022 97.6% of Meta’s revenue has come from ads.) 

The chances are slim that a successful company which invented an industry can use its money to invent a new one. Apple, I guess, is the only real example of that, and even then each new industry they create or permeate depends hugely on the success of their existing ones. There’s little point in selling services and apps if you’re not also selling the hardware they’re being distributed on.

So where might the new ideas come from? For now we’re still too interested in the technologies, not the use and users of them. All the technologies of the early noughties — blogging, RSS, tagging, wikis — arose out of frustrations with what was on offer. None had a business model or an exit strategy in mind. At present I don’t see anything really similar happening. None of us seems to be asking the question: what are we frustrated with now that could be solved by better technology? Or perhaps more specifically — how could existing technologies be built up on or re-thought to make them more useful to as many users as possible? 

These are not necessarily simple questions. Partly the net is the victim of its own success. When I was writing about technology in the noughties, my main concern was to demystify technology, to make it accessible and less frightening. Now almost the opposite is required: the net has morphed from a fairly egalitarian, self-policed environment to one that is heavily controlled and directed towards extracting as much from the user as possible, be it directly or indirectly. That monetisation is largely built on the shoulder of the pioneers of the early 2000s. And so it’s unsurprising that the only real innovations Big Tech is interested in now is trying to build extra, new business models and industries atop its own dominance. 

So, instead of looking for how technology can be tweaked for greater individual utility and satisfaction, we’re just looking at what technologies can be harnessed to replicate the conjuring trick that Google, Facebook and others managed before: to convert a function (search, school yearbooks) into something that can be monetised. So we see lots of interfaces for the same service — Google Glasses, Meta’s VR Metaverse. This is the old-fashioned hammer looking fora. nail. 

So is there anything else? A few folk would point to blockchain as a valid and successful technology (through Bitcoin) which really was built to solve a problem we have — transferring value without having to submit to an intermediary. But that is both a blessing and a curse: Both the ICO era and the more recent DeFi era have shown that when there is a financial use case for a technology it will likely be diverted into opportunities for plunder.  Those who understand it better than most will develop products that are essentially grifts, in that those who understand them better will make money at the expense of those who understand them less.  That’s not to say there are some promising uses of blockchain, and the DeFi infrastructure built atop them, but they need to be developed by people not all looking for a big and quick payday, rug pull or otherwise. This crypto winter may provide some breathing space for them to do so. (Please see my declaration of interest at the bottom of this post). 

And so here’s the rub: Silicon Valley is in the way here, just as their absence during 2000-2004 really helped some good ideas thrive and take flight, even if many of them ultimately ended up being bought by Big Tech and lost in a cupboard somewhere. We learned back then that a good idea doesn’t need a lot of funding; it needs a handful of smart people uninterested in an exit. I do see a few of these people, including in DeFi. At some point it may be healthier and more productive to lower one’s sights — to stop thinking that they need to build a new financial system. A new financing system, perhaps, but just solving some of the problems ordinary users face, without it necessarily changing the world. RSS didn’t save the world, but there’s a lot we wouldn’t have now if it didn’t exist. 

—

Declaration of interests: I consult for a PR agency, YAP Global, which focuses on crypto, web3 and DeFi clients, and I have in the past consulted directly or indirectly for Facebook, Google, and some other tech companies on issues related to this subject. I hold some crypto assets. Thanks to Gina Chua for ideas. 

Coming to terms with terms (Digitisation)

By | June 19, 2022

There’s lots of grey when it comes to three terms that as a journalist I used rarely because they were such turn-offs to readers and editors alike. But companies like them and they’re useful, up to a point, to help us understand this process we’re going through.

The terms are digitisation, digitalisation and digital transformation.

Yes, they’re horrible.

One reason they’re horrible is they aren’t exciting. No way would an editor of mine have OKed a story with those words anywhere in it.

Another reason is they’re very similar, in both sound, and definition. Nobody seems to agree on what they are, which is usually a good sign you’re veering into marketing/consultant-speak. When a term is not one that people use in public confident that everyone in the room understands it and agrees with everyone else what it means, you

a) shouldn’t use it and

b) should assume it’s dreamt up by some fella to sell more widgets (or consulting time.)

As a consultant I’m offended by that so I’m going to take a stab at defining it. It’s not that the concept is hard, it’s that the terms, I feel, aren’t particularly helpful.

So here’s my stab at defining them, in the hope that they actually demonstrate something useful, which is presumably why we have them. (And yes, arguably we should ditch them.)

The world is still largely analog

The natural world is analog. In the words of Peter Kinget, Department Chair of Electrical Engineering at Columbia University:

The world we live in is analog. We are analog. Any inputs we can perceive are analog. For example, sounds are analog signals; they are continuous time and continuous value. Our ears listen to analog signals and we speak with analog signals. Images, pictures, and video are all analog at the source and our eyes are analog sensors. Measuring our heartbeat, tracking our activity, all requires processing analog sensor information.

For most of us this is an ongoing process. We are forever asking our devices to convert the analog world to digital. But let’s keep it simple: suppose we have a cupboard full of old photographs. Or slides. Or negatives. They are, obviously, analog. We can still look at them, hang them on the wall, put them in an album, print off the negatives, show the slides on a projector, but all of those are analog processes. The data has not been changed.

So we are still keeping both the data — the photos, slides, negatives — and the process analog.

You may be quite happy with that arrangement (I am — I can never throw out analog photos, they seem to be quite a durable medium) but the pressure is on to digitise. So we go about converting that data to digital by scanning them. This is an analog-digital process.

This all might seem rather basic, and it is. But it gets more complicated when we talk about more complicated digitisation. When a library digitises its books that is obviously using a similar process. But when it digitises its catalog, but not its books, it gets more complicated, as we shall see. How useful are the terms when an enterprise only digitises half of the process?


And there’s another problem. As I mentioned, we’re living in an analog world. And so a lot of our supposedly digital tools are actually largely performing the same task as the scanner in our photos example. But in real time, all the time. Take our cellphone, for example. More of the chips in there are actually ‘analog chips’ than digital ones. An analog chip will handle power supply to produce a well-regulated supply of power to other chips, wideband signals, and sensors. Or they may combine with digital chips to convert analog to digital (a temperature sensor, say) or from digital to analog — for making sound, for example.

According to Cricket Semiconductor, there are more than twice as many analog chips as digital ones. (Cricket itself might no longer be with us, and the iPhone model is a very old one, so this proportion might be out of date.)

These chips are forever converting real world data into digital data, from where you are, to how you’re holding the device, to where you’re touching the screen, what you’re watching, listening to, taking photos of, as well as some of the actual communication between your device and the outside world. Digitisation, in other words, is not necessarily managing a step but managing a continuous process. This bit, I believe, is why we run into problems with the next two terms.

If it’s digitised, it can be digitalised

Yes, an ugly aphorism, but the idea is a simple one: Unless you’ve gone through the digitisation stage, outlined above, you can’t start to reap the benefits of digitisation. Which is what we call digitalisation. Not all of us, but let’s for the moment leave them out of it.

Going back to the pile of photos. You’ve scanned them into the computer and they’re all now bits, noughts and zeroes. And you can look at them on your computer, or phone, or whatever you used to scan them. But they’re not digitalised, as it were. Once again, this is both a data and a process.

  • First you would be renaming the photo files to something useful — usually a date, perhaps with some idea of who is in the photo.
  • Then you might be adding some metadata — data about the data (in this case a photo).
    • You might do this manually — adding details to the file itself (i.e. not the filename, but the fields that accompany the JPEG format, or whatever format you’ve chosen to store the file in.) These could include location (geolocational data, usually in the form or coordinates), type of camera, date the photo was taken, subject matter. Anything you like.
    • Some of this process might be automated — for example, dumping the photos in Apple Photos, and letting it scan the photos for faces, and then grouping those files together when it recognises your Aunt Maude is in them. (In more complex examples, the digital images can be explored using something called computer vision, which is essentially training a computer to see a digital image and work out what it contains — whether it’s a dog, or a traffic light etc.)

Now this is, in my view, part of digitalisation, not digitisation, although you can see how this might be argued either way. To me you’re now already into the process of adding value to digital data by adding metadata to the photos, which is to me the key element of digitalisation. We’re adding data to the data so it can use, and be used by, other data and processes (what we call applications.) We can now search for photos of Aunt Maude and find her without having to remember when we last saw her, and so which box of photos or albums to hunt through, or if the photos were digitised but still lacking metadata, trawling through hundreds of thumbnails until we spotted her glistening red beehive.

Going back to the iPhone, this process of digitalisation is tightly woven into the process of digitisation. When our phone is busy converting real world, analog, information and signal into digits, that is just a conversion process. When that process is finished (which of course it never is, but I’m referring to individual sessions of conversion) then the digitalisation — the digital dividend — kicks in. For the iPhone that is seamless and largely expected — after all that’s the point of the device, a pocket full of real-world tools and applications — but the digitisation is still a process that has to happen. It’s just so quick and seamless we don’t realise that it’s two processes: digitisation and digitalisation. The capturing of real world data and converting it to digits, and then adding value to those digits by turning them into usable data. (The computer vision process mentioned above could also be compressed — photos and video are shot and analysed in almost real time, because they may well need to be. The automated or connected car needs to know whether it’s about to hit a dog in the road, as the below GIF shows.)

Digitalisation is a multi-step process

Now digitalisation doesn’t stop there. When data is digital it can now start talking to other digital data. Other applications can understand that data, combine it with other data, and create new data, and thereby add value. In our photos example, the photos — or usually the underlying metadata — can be connected with other applications, such as search engines, or databases, or virtual reality games.

In the case of the phone, all that real world data about heat, position, moisture, sound etc can be used by dozens of applications on your phone. Without that real world data the phone is surprisingly dumb. (And even wifi and GPS signals require some amount of analog to digital conversion.)


Now some would argue this is also ‘digital transformation’ because, when it comes to business, processes are being transformed by the digitisation dividend. By converting analog to digital and using that data it’s argued that digitalisation is synonymous with digital transformation. I don’t buy that, it strikes me as lazy shorthand and not properly looking at the stages involved:

  • Digitisation has converted atoms to bits;
  • Digitalisation has converted those bits to data that can be interpreted and used by the rest of the digital world (within the device, the house, the company, the world).

And yes, just as digitisation was also both data and process, part of that is also the process of making use of these digital assets. But it’s not ‘transformative’, at least in the sense I understand it.

Take the library: they digitised the catalog. Great.

But no biggie. People still have to go find the books on the shelves; they are just able to confirm its existence more readily — and in theory remotely.

Then the librarians converted the entire library to digits, scanning every book.

Better; now I can read the book on my iPad, in theory, and I don’t need to go to the library. Good. But. I would argue that’s digitalisation more than digital transformation. They may have transformed their own procedures, but not yet undergone digital transformation.

Let’s see why.

Digital transformation is, or should be, when processes and businesses are transformed

So let’s start with the library this time. It’s not going to take long before people realise that you don’t actually need a physical library (at least for storing books).

Or librarians.

Or even digital books. Why not just let people search the text and metadata of books digitally and put together whatever collection of reading, or notes, or insight they want?

Why not convert the librarians into curators, who develop systems to connect disparate subjects and disciplines together, training algorithms to think better than we humans about the links between subjects? Or to mine data from readers to better understand and recommend more books to them, or figure out how to encourage people to read more?

Whole new services could emerge from what we used to think of a staid environment wedded to slumber and the worship of dead trees. (And, yes, we could use the libraries for something else: poetry, education, talks, a post-prandial nap, advice.)


This is what I think is meant by digital transformation. It’s a long drawn-out process that we’re only beginning to touch the edges of. It embraces things like automation, Internet of Things, AI, biomimicry (because it’s about converting the real world into something we can use, and better understand, and biomimicry is exactly that).

Digital transformation is taking data that can now be connected to any other kind of (digital) data, and build new ideas, business models, industries, disciplines etc, that weren’t available or apparent to use before, so it makes sense that the real value is going to lie in places we haven’t dreamed of yet.

That’s the distinction I make between digitalisation and digital transformation. Digitalisation is the process of adding value to digitised data, improving business processes, making them more efficient. Digital transformation is the process of transforming how that data is used in innovative ways that change industries entirely.

In short:

  • You can’t digitalise any process until the data it spews out has been digitised.
  • You can’t transform a process until you’ve digitalised it — applying digital technologies to the data you’ve digitised.
  • When you transform a process you change it fundamentally, recognising and realising the opportunities digitalisation could unleash.

So, a final example to clarify what I think are the differences.

Let’s take a heat sensor (thermometer) attached to a machine.

The sensor readout itself could be digital, but if you’re writing down the readings in a book the data becomes analog. It needs to be digitised — entered into a tablet, and then into a spreadsheet, say. Or the data could be drawn straight from the sensor itself. That is, arguably, digitisation. I would argue it’s digitisation because it’s still part of the process of converting analog data into digital. I would say that unless you’ve got to the point where all your key data are digits, you’re not digitised.

Once the data is there, you can digitalise both it and the processes. The first step is converting it to a form that is intelligible to the rest of your processes. The data has now been digitalised. And then, the next step of digitalisation is to digitalise the process — where the sensor is read by a computer and an automated warning light goes off to signal when there’s a problem.

Digital transformation occurs when this process is overhauled so that the business itself is transformed. It might just be transforming the process — robots replacing workers, say — but that is just a step in a much longer process when you don’t just replace one sort of tool with another, but actually change the way the widget is made, or sold, or change the widget itself. In the case of the sensor, it would be first to automate not just the monitoring and warning process, but then automating the repair work, the replacement, or using AI to learn how to improve the lifetime of the machinery, or the optimal process for replacement in conjunction with other data about other machines, prices, time of day etc. The next step would be redesigning the machine itself based on the lessons drawn from the digitalisation. It could be to transform the business entirely, by using the data to improve the business model (XaaS), using different processes, or to get out of the business altogether.

Digital transformation is a journey (much as I hate the word, which business has rendered meaningless or obfuscatory, depending on the context), not a step.


I am well aware that I am not using the terms as some use them. And I am happy to be corrected by those who can show me I’m misunderstanding the underlying processes. But hopefully this will prompt a discussion, or at worst some brickbats.